
Mixture of experts
A mixture-of-experts (MoE) layer holds several feed-forward networks, called experts, in place of one. For each token, a router scores the experts and selects the top_k with the highest scores, and the layer sums those experts’ outputs weighted by the scores. To make a CausalTransformer sparse, set its mixture field to a Mixture from dew.nn.backbones.
Example
Section titled “Example”import jaximport jax.numpy as jnp
from dew.nn.backbones import CausalTransformer, Mixture
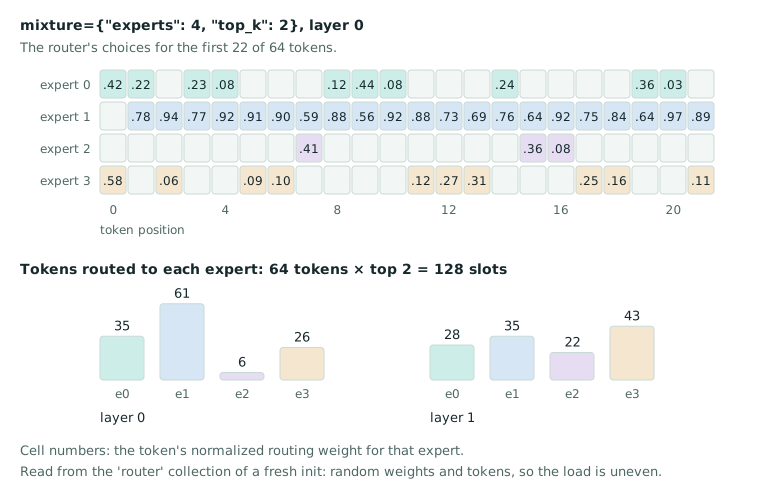
model = CausalTransformer( vocab_size=32, emb_features=16, num_layers=2, num_heads=2, mlp_features=32, max_seq_len=8, mixture=Mixture(experts=4, top_k=2), dtype=jnp.float32, attention_impl="xla",)tokens = jnp.array([[1, 2, 3, 4]], dtype=jnp.int32)variables = model.init(jax.random.key(0), tokens)logits, routed = model.apply(variables, tokens, mutable=["router"])print("logits:", logits.shape)chosen = routed["router"]["layers_0"]["mlp"]["gate"]["indices"][0]print("experts per token, layer 0:", chosen[0].tolist())logits: (1, 4, 32)experts per token, layer 0: [[1, 3], [3, 1], [1, 0], [3, 2]]Every layer here routes to two of four experts, and the logits keep the usual (batch, sequence, vocabulary) shape. Passing mutable=["router"] makes each router record its choices (indices, [batch, sequence, top_k]), its scores and its log partition; without it nothing is recorded. Flax stores sown values in a tuple, which the first [0] unpacks. The figure reads the same collection from this model over 64 random tokens.
Mixture
Section titled “Mixture”| Field | Default | Meaning |
|---|---|---|
experts | required | Number of experts. |
top_k | 2 | Experts per token. |
layers | None | Sparse layers by index; None makes every layer sparse. A checkpoint’s cadence (Qwen3-MoE’s decoder_sparse_step, Llama 4’s interleave_moe_layer_step) translates to these indices. |
score_function | 'softmax' | How router logits become scores. |
norm_topk_prob | True | Divide a token’s selected weights by their sum. |
scaling | 1.0 | Routed output scale. |
groups, groups_per_token, group_score | 1, 1, 'top2' | DeepSeek’s group-limited routing. |
bias | False | Keep an aux-loss-free balancing bias (DeepSeek’s e_score_correction_bias). |
expert_features | None | Expert width; None uses mlp_features. |
shared_features, shared_gate | 0, False | Width of one dense shared expert every token takes, and a learned sigmoid gate on it. |
parallel | False | Gemma 4’s placement: experts beside the dense MLP. |
implementation | 'auto' | Grouped matmul kernel: 'auto', 'xla' or 'pallas'. |
dispatch | 'global' | 'global' or 'exchange' (expert parallelism). |
capacity_factor | None | Per-expert slot capacity; None keeps every selected slot. |
hash_layers, latent_features, latent_norm, media_bias | DeepSeek V4 hash routing, Kimi K3 latent experts, DeepSeek-V4.1’s media bias. |
When you load a published checkpoint, its configuration sets these values. Changing them changes the architecture and can make the weights unusable.
Routing
Section titled “Routing”Model families route in different ways: softmax or sigmoid scores, normalized or raw selected weights, output scaling, group-limited routing, shared experts and a selection bias. So two routers whose tensors have the same shapes are not necessarily interchangeable. The router’s gate projection runs in float32 whatever the activation dtype.
A router you train from scratch with top_k=1 and softmax scores needs norm_topk_prob=False. Normalized over the one expert it chose, a token’s weight is always 1, so the model’s loss never reaches the router’s scores: the router learns only from a balance loss or a z-loss, if you add one. An objective that would train such a router with neither is refused (dew.objectives.routing.refuse_fixed_router). Unnormalized, the weight is the chosen expert’s softmax score, and the router learns through it, as Switch Transformer’s router does.
To balance the load without an auxiliary loss, set bias=True. Each expert then gets a bias that is added to its score when the router selects experts, but not when it weights them. The bias is non-parameter state. LMObjective(balance=ExpertBalance(balance_rate=...)) moves it against each expert’s load at every committed update (dew.objectives.routing); MaskedDiffusionObjective, GRPOObjective, DPOObjective and PPOObjective take balance the same way, and the policy objectives count the response tokens they train. The balance loss (aux_loss_alpha) and the router z-loss (router_z_loss) are the other terms of that policy (Language models). Check the algorithm and configuration of your model family before you turn on either.
Routing replay trains on the experts that a rollout engine used (R3, arXiv 2510.11370). Pass routes=(routed_experts, routed) to LMObjective.token_scores, or, for GRPO, pack sessions whose calls recorded routed_experts (Post-training). The record has shape [batch, tokens, layers, top_k] and is indexed by decoder layer, the way vLLM and SGLang return it. Each router uses the recorded experts in place of its own top-k but still computes their weights from the scores of the current forward pass, so the router still gets a gradient. Where the record does not cover a token (routed is false, as for the last sampled ID), the router makes its own choice. A balancing bias counts the replayed experts.
Expert kernels
Section titled “Expert kernels”Dew sorts tokens into expert order and runs the experts as one grouped matrix multiplication. implementation picks the kernel:
| Value | Kernel |
|---|---|
'auto' | The GEMM template’s kernels wherever one of its launches takes the call, else XLA’s program. |
'pallas' | The same choice as 'auto': both leave it to the GEMM template (dew.nn.moe.expert_projection). |
'xla' | jax.lax.ragged_dot for every launch, which XLA runs as a product over every expert. |
The GEMM template chooses each launch where it runs, and reports each route with its reason (dew.nn.kernels.generation.route). Its order and the cells an older route keeps are the selector’s (Kernel templates: choice). generation.chosen(grouped_matmul=...) names one kernel, and a named kernel that cannot run the call raises KernelRefused. A CPU process runs XLA’s program. XLA’s ragged dot computes a product over every expert, so where the template’s kernels run they are much faster (Performance measurements). The template differentiates its launches at every order, so a Trainer step’s reverse mode, forward mode and higher-order derivatives (as in meta-learning) all run the same arithmetic.
The choice is the same on a mesh. The experts run inside the dispatch’s shard_map on each device’s rows, and the weights they need are gathered onto that device. Every routed expert module the decoder builds follows implementation, including GPT OSS’s.
Dispatch and expert parallelism
Section titled “Dispatch and expert parallelism”The expert mesh axis splits the expert dimension across devices. Dense parameter dimensions can use FSDP or tensor placement on their own; Distributed training covers the global batch and layout requirements.
dispatch='global', the default, sorts and gathers tokens on the device that already holds them. On a mesh, each device routes its own tokens through every expert, so every layout computes each token once.
dispatch='exchange' is expert parallelism. Each device sends its selected tokens to the devices that hold their experts in one JAX ragged_all_to_all, each shard receiving exactly the rows routed to it, and receives the results back in another. It needs an expert mesh axis larger than one that divides the number of experts; the data, fsdp and sequence axes may split the tokens further. The exchange keeps every selected token, even when all of the traffic goes to one shard: a shard’s receiving buffer holds every device’s slots.
You can initialize the model outside a mesh, but applying the exchange needs the mesh. TextGeneration refuses dispatch='exchange' (Inference), so generate with dispatch='global', which computes the same layer. Gated experts and GPT OSS’s interleaved biased experts are exchanged the same way, and each keeps its own activation and output-weight arithmetic.
To drop tokens over a fixed capacity, as GShard and MaxText do, set capacity_factor. Each sequence keeps max(ceil(length * top_k / experts) * capacity_factor, capacity_factor) slots per expert, filled in token order, and a dropped slot adds nothing to its token’s output. Because the count runs over whole sequences, both dispatch modes drop the same slots on every placement. With a capacity set, a shard’s receiving buffer holds what the capacity keeps.
Precision
Section titled “Precision”Both dispatch modes run their expert projections through moe.expert_projection. It gives a routed layer the same rounding in training whatever the activation dtype and placement:
- each contraction accumulates in at least fp32 and rounds once to the compute dtype;
- a kernel gradient sums the shares from every device and every exchange round in at least fp32 and rounds once to the master dtype; the summation order still depends on the mesh, so gradients on different meshes agree to fp32 rounding but not bit for bit;
- kernel gradients keep the master dtype, and input gradients their input’s dtype;
- the exact GELU rounds once.
A model that names no dtype computes its experts in their stored dtype when that dtype is narrower than the residual stream (moe.expert_compute_dtype). For example, with an fp32 stream and bf16 expert kernels, each expert’s input is rounded to bf16, the experts multiply bf16 by bf16 with fp32 accumulation, and they return bf16. The dense layers of such a model still promote to fp32. Promoting the experts to fp32 as well would copy each layer’s kernels; serving gpt-oss-20b on four RTX 3090s, those copies took 14.35 GiB of live temporaries. So the forward pass reads the kernels as stored, and only a gradient widens them, because its cross-device sums need fp32.
JAX’s x64 mode also widens default integer counts to int64. The TPU ragged-dot kernel cannot lower int64 indices, so the XLA grouped-matmul path narrows signed int64 group sizes to int32 when the number of rows fits. The expert values and their gradients keep the dtypes above.
Forward-mode and reverse-mode differentiation follow the same rules. tests/test_moe_precision.py checks them against float64 arithmetic on the rounded operands, and over three Adam steps of both dispatch modes in bf16. tools/moe_exchange_probe.py compares the exchange’s working memory with the global path’s on CPU; it does not measure throughput on several accelerators.
GPT OSS’s per-expert biases go through moe.expert_projection’s bias: the GEMM template’s epilogue adds each expert’s bias to its rows’ fp32 sums before their one rounding, reading the bias at each row’s expert, and sums its gradient over each expert’s rows at master or compute precision before converting it back to the parameter dtype. transformers’ bf16 GptOssExperts rounds the product to bf16 before adding the bias and rounds again, so the one rounding here is the closer of the two to float64. Padding and idle experts add no bias gradient. The stored fused kernel and bias leaves, router choices, clipping limits and SwiGLU scaling are unchanged. tests/test_moe_biased_exchange.py checks the full router and experts against pinned transformers fixtures, and compares the forward pass, backward pass and optimizer updates of both dispatch modes.
Cost and validation
Section titled “Cost and validation”More experts need more parameter storage, even with a fixed top_k. Routing, communication, shared experts and load imbalance all add to runtime. Every expert’s weights stay in accelerator memory: streaming experts from host memory or SSD, as a trillion-parameter model would need, is deferred, not dropped. Estimate the optimizer and EMA storage along with the parameters, and time a representative forward and backward step on the topology you plan to use.
Against a reference model, compare the router’s selections and weights, the sparse layer output, the loss and the parameter updates. For distributed training, check that the balancing statistics cover the global batch and that replicated state stays identical across shards. Supported models lists which sparse checkpoints load and which have no export writer.